Runhui Huang (黄润辉)
huangrh9@gmail.com
Hi, I am currently a PhD student at the University of Hong Kong, under the supervision of Prof. Hengshuang Zhao. Previously, I received my Bachelor's degree (2021) and Master's degree (2024) from Sun Yat-sen University, where I was supervised by Prof. Xiaodan Liang.
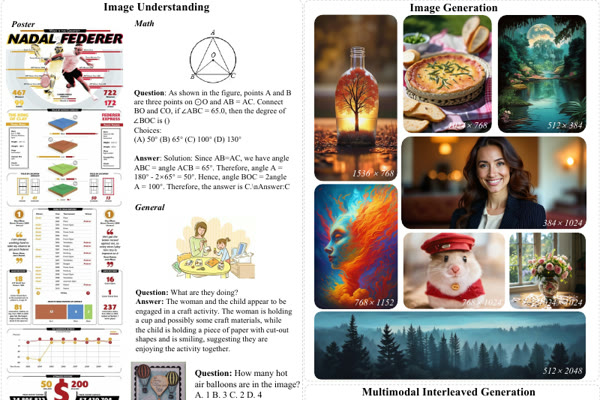
My research focuses on Unified Multimodal Understanding and Generation, with broad interests in vision-language pre-training and post-training.
More about me: Google Scholar / Github
Research Interests
- Unified Multimodal Understanding and Generation
- Reinforcement Learning for Multimodal Models
News
- [07/2026]We released SpectraReward, a training-free reward model for text-to-image generation.
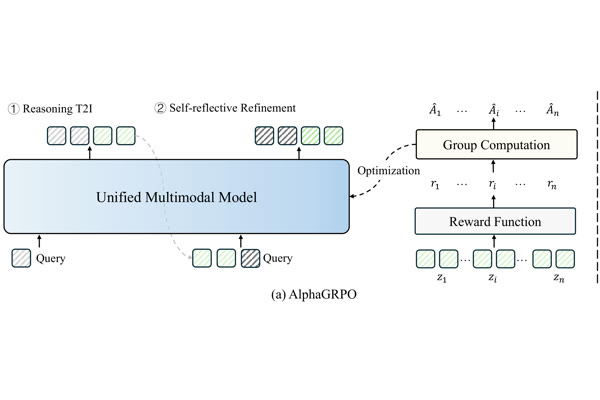
- [05/2026]AlphaGRPO was accepted to ICML 2026.
- [09/2025]I joined ByteDance Seed as a Research Intern.
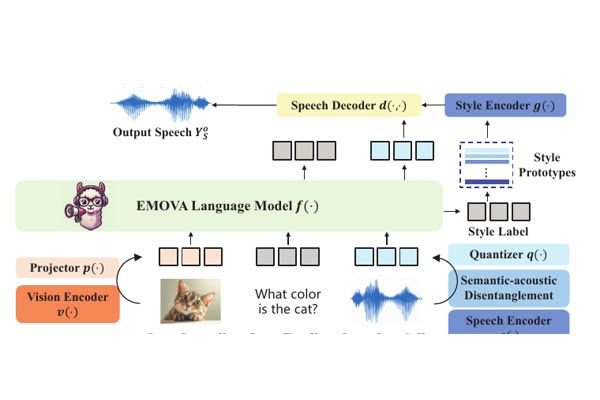
- [02/2025]Two papers, HiRes-LLaVA and EMOVA, were accepted to CVPR 2025.
- [09/2024]I started my Ph.D. at HKU.
- [09/2024]I joined Huawei Noah's Ark Lab (Hong Kong) as a Research Intern.
- [07/2024]LayerDiff was accepted to ECCV 2024.
Selected Publications [Google Scholar]
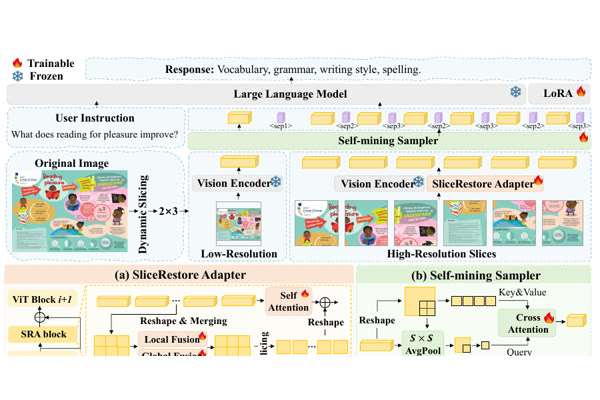
HiRes-LLaVA: Restoring Fragmentation Input in High-Resolution Large Vision-Language Models
Runhui Huang, Xinpeng Ding, Chunwei Wang, Jianhua Han, Yulong Liu, Hengshuang Zhao, Hang Xu, Lu Hou, Wei Zhang, Xiaodan Liang.
CVPR, 2025.
[paper]
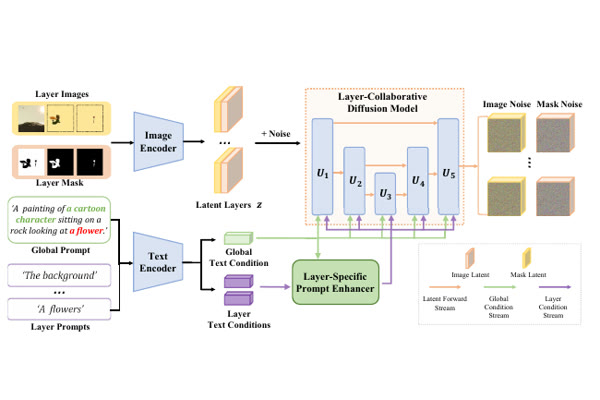
LayerDiff: Exploring Text-guided Multi-layered Composable Image Synthesis via Layer-Collaborative Diffusion Model
Runhui Huang, Kaixin Cai, Jianhua Han, Xiaodan Liang, Renjing Pei, Guansong Lu, Songcen Xu, Wei Zhang, Hang Xu
ECCV, 2024.
[paper]
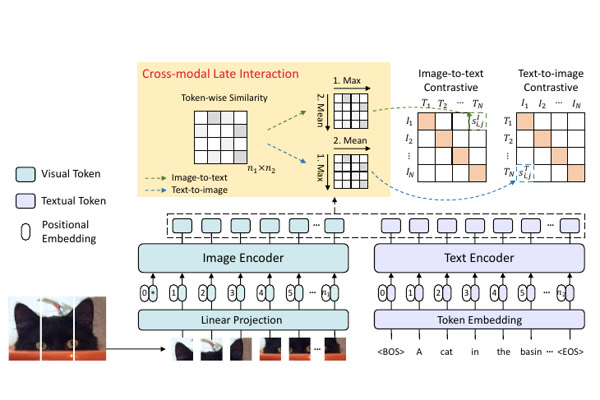
FILIP: Fine-grained Interactive Language-Image Pre-Training
Lewei Yao∗, Runhui Huang∗, Lu Hou∗, Guansong Lu, Minzhe Niu, Hang Xu, Xiaodan Liang, Zhenguo Li, Xin Jiang, Chunjing Xu.
International Conference on Learning Representations (ICLR), 2022.
[paper]
Selected Honors
- 2023 Academic Innovation Scholarship, Sun Yat-sen University
- 2022 Outstanding Student Scholarship (First Class), Sun Yat-sen University
- 2019 Second Prize, National College Student Mathematical Modeling Competition (Guangdong)
Professional Activities
- Reviewer: CVPR 2023-2026, ICCV 2023/2025, ECCV 2024/2026, ICLR 2025-2026, NeurIPS 2024-2025, ICML 2026 (Gold Reviewer)